AI Checker
Plagiarism Checker
Grammar Checker
Content Quality
Guideline Checker
Readability Checker
Fact & AI Hallucination Checker

Extensions
MCP

Following the release of Claude Fable 5 earlier this year, Anthropic released Claude Fable 5.2 on November 9, 2026.
We tested whether Originality.ai 5.0 could recognize its writing as AI-generated by studying 1,000 English responses from Claude Fable 5.2.
We routinely test new LLMs from leading AI companies as they are released. Visit our AI Studies page for even more insights into Originality.ai’s accuracy.
Yes. Originality.ai 5.0 classified 1,000 of 1,000 Claude Fable 5.2 responses as AI (100%). It returned 0 Mixed and 0 Original verdicts.
We started with the prompt bank from our Gemini 4 Argon study. The English prompts covered blog posts, conversation, expository writing, news, and reviews, with 200 responses per category. Some prompts asked for rewrites or a more human writing style.
We generated and scanned the responses on November 11, 2026. We used the Claude API at High effort with an 8,192-token output limit, no tools, and no added system prompt. We kept one complete, substantive response per prompt.
Before scanning, we replaced 24 prompts within their original categories because the responses were unusable. The final responses ranged from 249 to 2,179 words (median 846).
We scanned each full, unedited response once with Originality.ai 5.0.
All scans succeeded. The benchmark counted AI and Mixed verdicts as detections. Every detection received the AI verdict, so the AI-only rate was also 100%.
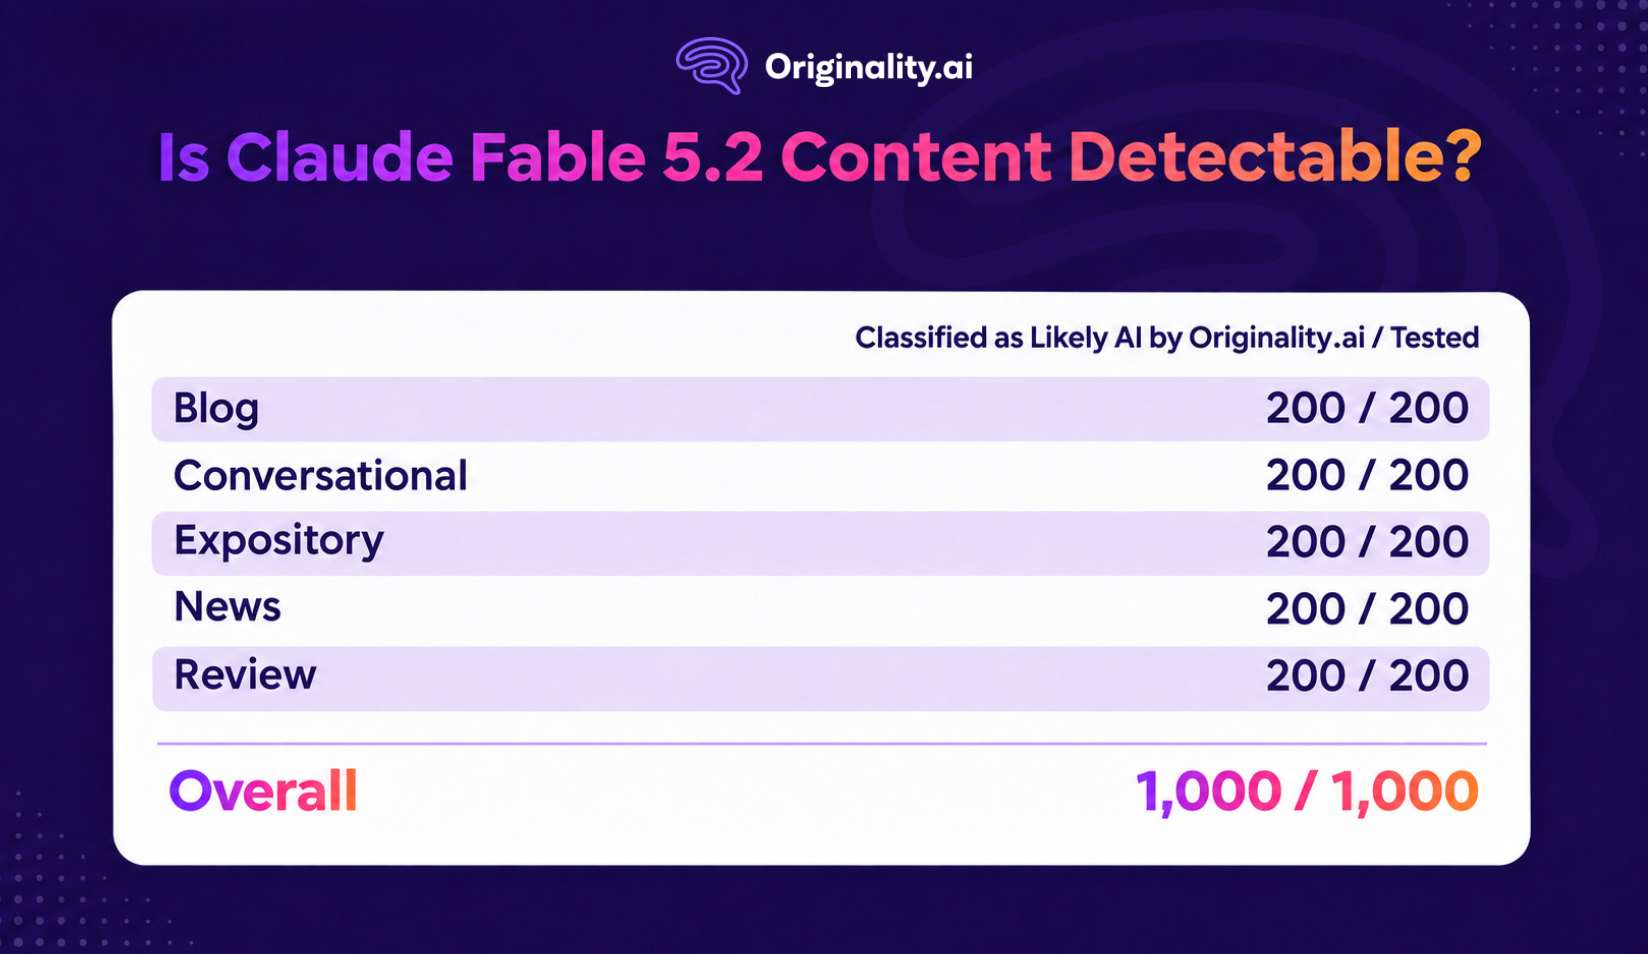
The key finding then? Originality.ai accurately detected 1,000/1,000 Claude Fable 5.2 samples as Likely AI.
With the rapid releases of new LLMs from leading AI companies like Anthropic, it’s essential for AI detectors to continue testing their efficacy.
So, as soon as Claude Fable 5.2 was released, we studied whether Originality.ai 5.0 could still detect its AI-generated content.
Our finding was that Originality.ai 5.0 could accurately detect all 1,000/1,000 Claude Fable 5.2 samples tested as Likely AI.
For editors, writers, students, and teachers looking to maintain writing transparency, Originality.ai is a highly accurate way to identify AI-generated text from the latest LLMs like Claude Fable 5.2.
Read more about studies on recent AI models:
Learn about 3rd-party studies on Originality.ai AI Accuracy:
This study measured how often the detector identified known AI writing. The sample contained no human-written controls, so it cannot estimate false positives or overall accuracy. Use detector verdicts as a signal for review alongside other evidence.
The result held on the 976 unchanged prompts and the 999 responses of at least 300 words. All 908 responses from prompts with no substitutions or length adjustments were also classified as AI. These groups overlap.
Anthropic says Fable 5.2 API text carries a watermark. We scanned the model’s normal output, so the study cannot isolate any effect of watermarking.
Math Papers on arXiv are rapidly increasing. In our latest update, Originality.ai found: from October 2025 to October 2026, there was a 115.5% surge in new papers. Further, nearly 1 in 4 sampled abstracts showed signs of probable AI writing.

AI & Plagiarism Detector for Serious Content Publishers
Originality.ai
64 Hurontario St
Collingwood, Ontario
L9Y 2L6